OwnGenome
OwnGenome was called Personal-Genome-Pipeline until November 2026.


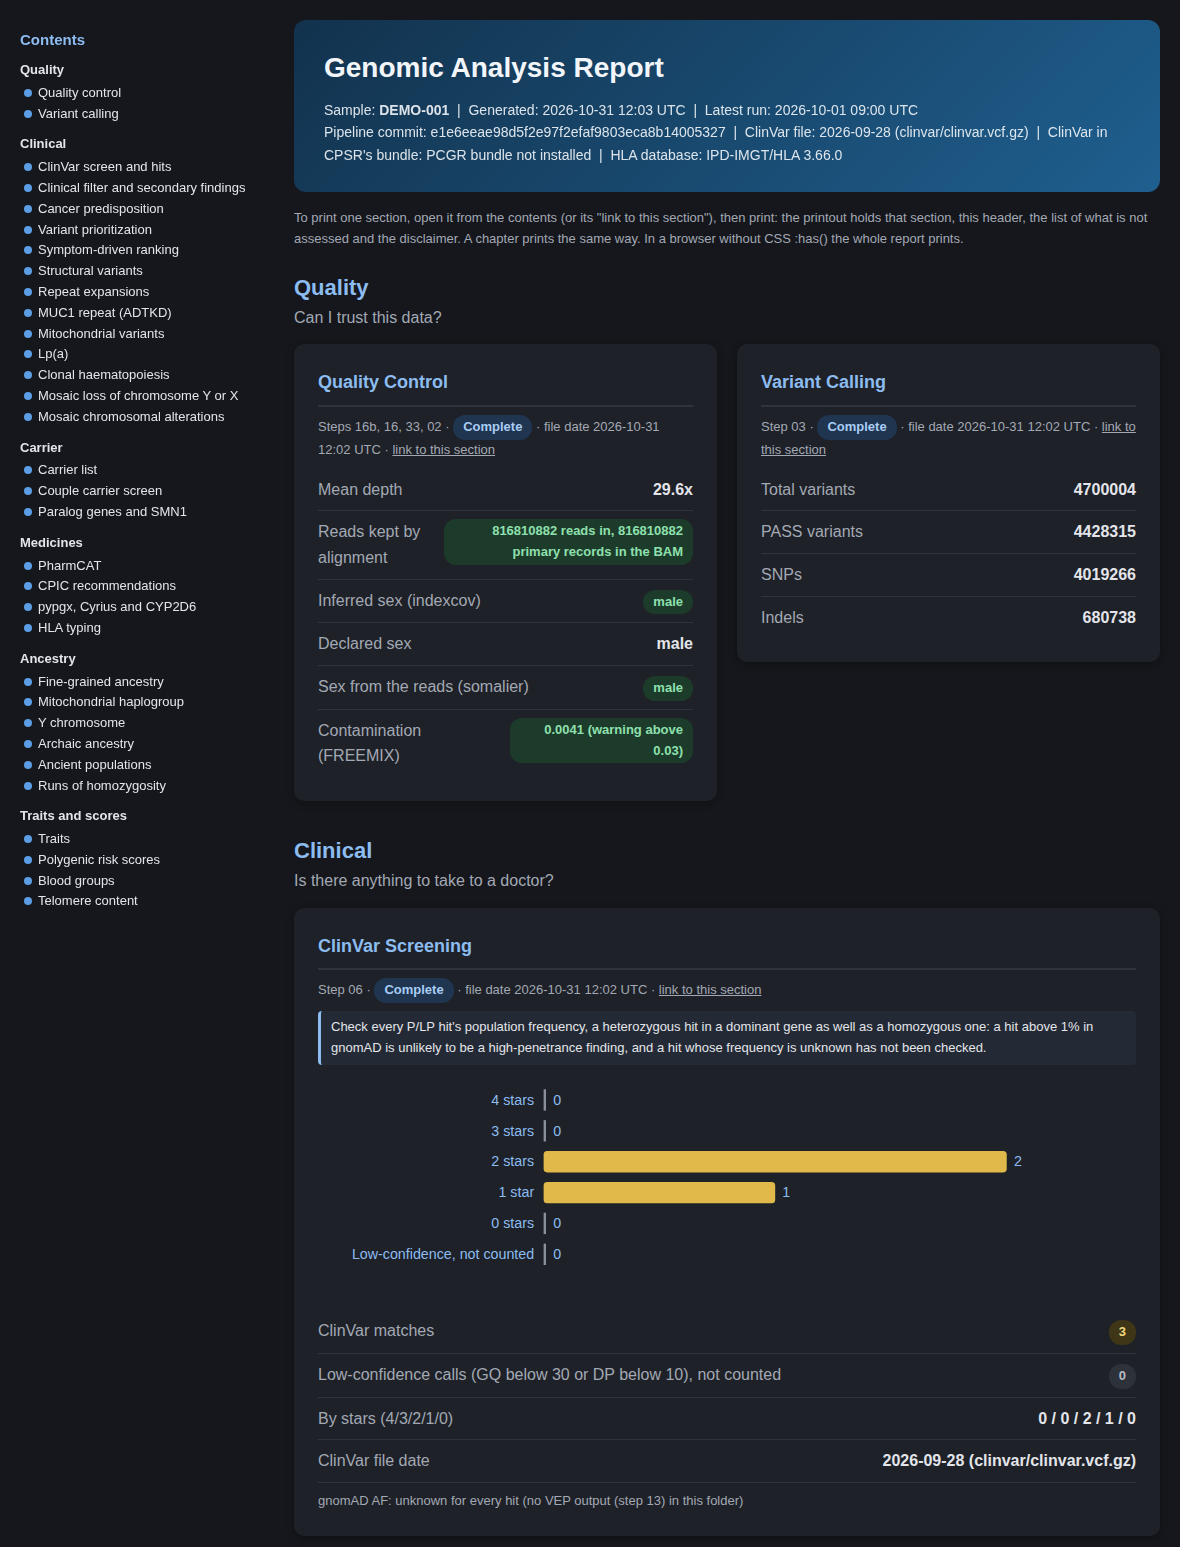
OwnGenome turns the files a consumer sequencing vendor gives you (FASTQ, BAM, VCF or Illumina ORA) into a full genomic profile on your own computer: small and structural variants, ClinVar and cancer-predisposition screening, pharmacogenomics, repeat expansions, HLA type, telomere content, mitochondrial haplogroup and heteroplasmy, runs of homozygosity, ancestry and polygenic risk scores. A vendor's own report covers a fraction of this and keeps your genome on their servers; a clinical lab charges per panel. Here every step is one Docker container with a hard memory limit, run by a Nextflow pipeline (scripts/run-all.sh starts it for one sample) or from one bash script per step, and no script sends your data anywhere. Start with Getting started, then run the quick test on public data before your own.
-
Prerequisites, the four entry paths (FASTQ, BAM, VCF, ORA), the first run and what "it worked" looks like.
-
Run the pipeline on a small public sample first, so a setup problem shows up in minutes, not a day into the run.
-
Every step with its tool, its image and whether it is required, which steps a default run includes, plus the pipeline graph.
-
What each report means, what is normal, what needs a genetic counsellor, and what to re-run when databases update.
What it finds
- Small variants: SNPs and indels with DeepVariant; structural and copy-number variants with Manta, Delly and CNVpytor merged into one consensus set.
- Clinical screening: known pathogenic variants from ClinVar, cancer predisposition panels with CPSR, VEP annotation with CADD, SpliceAI, REVEL and AlphaMissense, and slivar prioritisation of rare deleterious variants.
- Pharmacogenomics: PharmCAT and pypgx star alleles (pypgx: 29 genes, 13 of them with copy number from the BAM), CYP2D6 structural alleles with Cyrius, CPIC dosing recommendations.
- Ancestry and lineage: mitochondrial haplogroup and heteroplasmy, runs of homozygosity, ancestry placement against the 1000 Genomes panel (optional download), the Neanderthal and Denisovan segments you carry (optional download), polygenic risk scores for 13 conditions and traits.
- Everything else the reads hold: clonal haematopoiesis (CHIP) in the blood, with the detection limit at your depth (opt-in), HLA type, repeat expansions at STRchive's 82 disease loci (Huntington's, Fragile X, ALS among them), telomere content, sex-chromosome check, coverage statistics, one HTML report and a MultiQC summary.
Pipeline steps
One page per step, grouped by stage. The step number is the script name and the output directory.
- Reads and small variants: 1 ORA to FASTQ, 1b fastp QC and trimming, 2 alignment, 3 DeepVariant, 3d Octopus (alternative).
- Structural and copy number variants: 4 Manta, 4b GRIDSS (alternative), 5 AnnotSV, 15 duphold, 18 CNVpytor, 19 Delly, 22 consensus merge, 50 mobile element insertions (opt-in).
- Clinical screening and annotation: 6 ClinVar screen, 13 VEP, 17 CPSR, 23 clinical filter, 29 somatic Mutect2 (opt-in), 30 vcfanno, 31 slivar, 48 Exomiser symptom-driven ranking (opt-in).
- Pharmacogenomics: 7 PharmCAT, 21 Cyrius, 27 CPIC lookup, 32 pypgx.
- HLA, repeats and telomeres: 8 HLA typing, 9 ExpansionHunter, 9b Stranger, 10 TelomereHunter.
- Ancestry, risk and mitochondria: 11 ROH, 12 mitochondrial haplogroup, 14 imputation prep, 20 mitochondrial variants, 25 polygenic risk scores, 26 ancestry, 26b fine-grained ancestry, 44 ancient populations.
- Quality control and reports: 16 indexcov, 16b mosdepth, 24 HTML report, 28 MultiQC.
Alternative callers for benchmarking (BWA-MEM2, GATK HaplotypeCaller, FreeBayes, Strelka2, TIDDIT) are scripts without a page of their own; Variant caller benchmarking covers how to run and compare them.
How it runs
graph LR
    FASTQ["FASTQ / ORA"] --> fastp["fastp"]
    fastp --> align["minimap2"]
    align --> BAM["Sorted BAM"]
    BAM --> DV["DeepVariant"]
    DV --> VCF["VCF"]
    VCF --> vcfsteps["ClinVar, PharmCAT, pypgx, VEP, CPSR,<br/>ROH, PRS, ancestry, haplogroup"]
    BAM -.-> vcfsteps
    BAM --> bamsteps["Manta, Delly, CNVpytor, ExpansionHunter,<br/>HLA, telomeres, Cyrius, mosdepth"]
    vcfsteps --> report["HTML report + MultiQC"]
bamsteps --> report- Each step is one
docker runwith an image tag or digest fromversions.env(listed on Image versions) and a hard memory limit. CPU is a hard--cpuscap in the single-step scripts; in the pipeline it is a Docker share, so an idle machine lends a step every core and a busy one shares them by weight (a shared host). - Two ways to run it:
./scripts/run-all.sh <sample> <male|female>starts the Nextflow pipeline, which runs independent steps in parallel and resumes after a failure (Full run); or one bash script per step underscripts/, with Docker alone. - A default run from FASTQ took about 20-21 hours on a 16-thread server, measured on 30-40x genomes, and DeepVariant is most of it (8 h 50 min to 13 h 30 min). On 8 CPUs plan for more than a day (not measured). Hardware and storage requirements gives the per-step time, memory and disk figures; a 30X sample needs about 500 GB from a BAM and about 700 GB from FASTQ.
- After reference data setup a run downloads only a few public files, listed in Why run locally?. A BAM or VCF from your vendor skips alignment or variant calling; Getting started has the entry paths and Vendor compatibility the per-vendor notes.
What it does not do
- It is not a medical device and has not been clinically validated. Findings go to a genetic counsellor or physician before any decision; the pipeline uses the same tools a clinical lab uses, but without a lab's validation and confirmation.
- PRS percentiles and the closest reference population need the optional 1000 Genomes panel (
setup.sh --ancestry-panel, about 7 GB); without it step 25 reports raw scores only. A percentile is not a risk. Admixture fractions and a chromosome painting are the opt-in step 26b, against another panel, and the names it prints are clusters of reference populations, not nationalities. Step 25, step 26 and step 26b say what the numbers can and cannot support. - It does not call CYP2D6 reliably from a VCF alone; that gene needs the BAM-based callers (Cyrius, pypgx), and short-read WGS still misses some alleles.
- It does not impute. Step 14 prepares files for an external imputation server; sending them there is your decision.
Privacy
- Your reads, alignments and variants stay in
GENOME_DIRon your disk. No script uploads data. A run still pulls images and fetches a few public files; Why run locally? lists each one and what the HTML reports load when you open them. - The example outputs on these pages are invented or use placeholders. No page shows a real person's genotype, haplogroup, HLA type, score or sample name.
- Why run locally? compares the cost and the exposure of the alternatives.
Guides and reference
- Interpreting your results: what each report means and what to do with it.
- Genome viewer: open any finding in igv.js with your own reads, served from your computer only.
- Look up a variant, an rsID or a gene: your genotype at one site or every variant in one gene, with what the reports say about it.
- Multi-sample comparison: partners, siblings, parents; carrier overlap and shared variants.
- Long-read sequencing: Nanopore and PacBio HiFi entry paths and which steps change.
- Whole exome sequencing: what an exome can and cannot feed into the pipeline.
- Genotyping array data: 23andMe, MyHeritage and AncestryDNA files, converted correctly.
- Variant caller benchmarking: concordance and truth-set runs for the alternative callers.
- Common issues and FAQ, then the Troubleshooting guide: symptom, cause, fix, per step.
- Lessons learned: what failed during development and why the defaults are what they are.
- Tool selection rationale, the Glossary and Recommended resources for learning genomics.
Getting help
- Something broken: the Troubleshooting guide first, then an issue with the step number, the full error text, your platform and your input type.
- A security problem: follow the security policy, never a public issue.
- What is planned: the roadmap on GitHub. Sending a fix or a new step: CONTRIBUTING.md.
License
OwnGenome is released under the GPL-3.0-or-later license. It is for educational and research use; it is not a medical device.