Media downloads
The backup downloads media files next to the messages. Read Reversible or not before your first large run. Every media variable and its default is in Environment variables.
What is saved by default
With no media settings, the backup downloads every media type up to 100 MB per file:
| Type | What it is |
|---|---|
photo |
Photos |
video |
Videos |
video_note |
Round video messages |
animation |
GIFs |
voice |
Voice messages |
audio |
Music and other audio files |
sticker |
Stickers: pictures (.webp), animated stickers (.tgs) and video stickers (.webm) |
document |
Any other file |
webpage |
Link previews that carry a photo or a document |
Some kinds of media have no file. The backup stores them as rows and never downloads anything for them: contact, geo, venue, dice, invoice, story, giveaway, giveaway_results, geo_live, game and unsupported. What they hold lives in the message data, under a key named after the kind: a location's coordinates under geo, a contact's name, phone and vCard under contact, a poll's question, answers and results under poll as first captured, and so on. A poll's later votes and closing are kept beside it as snapshots. The backup and the listener both keep them, and a download filter never drops them. For messages archived before these details were kept, run backfill-details.
A location, a venue and a live location are the exception: the backup also keeps the small map picture Telegram's own servers render for the point, as the official apps show it, in the chat's media folder as map_<16 hex>.jpg or .png. It is one request per location, made once. It follows DOWNLOAD_MEDIA and SKIP_MEDIA_CHAT_IDS, and for the listener LISTEN_NEW_MESSAGES_MEDIA, but not DOWNLOAD_MEDIA_TYPES, DOWNLOAD_DOCUMENT_MIME_TYPES or MAX_MEDIA_SIZE_MB: the picture is a few tens of kilobytes. No other server sees the point. See Locations and contacts.
Reversible or not
Some settings only postpone a download. Others make the backup skip the file for good on messages it has already archived. Decide before your first large run.
| Setting | What happens to skipped media | Can you get it back later? |
|---|---|---|
DOWNLOAD_MEDIA_TYPES |
A row is written with skip reason filtered |
Yes. Relax the setting and the next run downloads it. |
DOWNLOAD_DOCUMENT_MIME_TYPES |
A row is written with skip reason filtered |
Yes. Relax the setting and the next run downloads it. |
MAX_MEDIA_SIZE_MB |
A row is written with skip reason oversize |
Yes. Raise the limit and the next run downloads it. |
DOWNLOAD_MEDIA=false |
No media row is written | No. Turning it back on only affects new messages. |
SKIP_MEDIA_CHAT_IDS |
No media row is written for new messages in those chats. Rows already pending when you added a chat are kept and marked filtered. |
Partly. Removing a chat makes the next run fetch its pending rows. Messages archived while it was listed stay without media. |
YOUTUBE_VIDEOS_DELETE_EXISTING |
Downloaded YouTube preview videos are deleted | No. They are not fetched again. |
A row skipped with a reason never counts as a failed attempt. It stays in the archive until you relax the setting.
No row means no second chance
The backup only fetches messages newer than its stored position in each chat. A message archived without a media row is never revisited for its file. If you are unsure, use the type, MIME or size filters instead of DOWNLOAD_MEDIA=false or SKIP_MEDIA_CHAT_IDS.
Settings
Turn media off
DOWNLOAD_MEDIA=false stops message media downloads. Messages are still archived, with no media row. The backup keeps downloading profile photos to media/avatars/ and custom emoji to media/_emoji/, so the media directory exists anyway.
Choose media types
DOWNLOAD_MEDIA_TYPES is a comma-separated allow-list of the types in the table above. Empty means every type. An unknown type name stops startup. The filter applies to the scheduled backup and to the real-time listener.
Narrow documents by MIME type
A MIME type names a file format, such as application/pdf. DOWNLOAD_DOCUMENT_MIME_TYPES narrows the document type to a list of them. Each value must be a full type/subtype. A document is downloaded when its MIME type is on the list, or when its file name ends in an extension that matches a listed type.
Startup checks the list:
- a wildcard such as
image/*or a bare extension such aspdfstops startup; - a type with no known extension is logged.
Set a size limit
MAX_MEDIA_SIZE_MB defaults to 100. Set 0 or a negative number for no limit. A photo counts the size of its largest rendition.
YouTube preview videos
A link preview for a YouTube video can carry the video file. The backup skips that file unless DOWNLOAD_YOUTUBE_VIDEOS=true, and writes no row for it. The message and its link card, with URL, site name, title and description, are archived either way. No file is saved for the preview, not even its thumbnail.
On every run, YOUTUBE_VIDEOS_DELETE_EXISTING=true deletes the preview videos that earlier runs downloaded, with their rows and transcripts. While DOWNLOAD_YOUTUBE_VIDEOS=true, the backup ignores it and logs a warning. The rows go first, then the files. A chat-folder entry stays while a row of another account still names it. With deduplication on, a shared file is deleted only when nothing refers to it any more: no media row or earlier media of any account names the file or holds its hash, and no chat folder links to it.
Skip media for some chats
SKIP_MEDIA_CHAT_IDS lists chats whose text is archived without media. SKIP_MEDIA_DELETE_EXISTING=true also deletes the media rows and files these chats already have. It runs once per process for each chat and cannot be undone. The backup deletes the rows first, then the recorded files and symlinks in the chat folder, and removes the folder when it is empty. A file or symlink that a row of another account still names stays, because every account's copy of a chat shares one chat folder. It keeps the files in media/_shared.
Chat descriptions
DOWNLOAD_CHAT_DESCRIPTION=true stores each chat's description or bio, and the member count of channels and supergroups. It costs one extra request per chat per run. A FloodWait is Telegram asking the client to wait before its next request. The first FloodWait stops description fetching for the rest of that run. The chats keep their stored descriptions.
Layout on disk
Media lives in media/ under BACKUP_PATH. With DEDUPLICATE_MEDIA=true, the default, each file is stored once and chat folders link to it:
media/
├── _shared/
│   └── 3f/
│       └── 5012345678901234567_report.pdf
├── -1001234567890/
│   └── 5012345678901234567_report.pdf -> ../_shared/3f/5012345678901234567_report.pdf
├── _emoji/
│   └── 5000000000000000001.webp
└── avatars/
    ├── users/
    └── chats/
- The real file sits at
media/_shared/<first two hex characters of its SHA-256>/<name>. - Each chat folder holds a relative symlink to it.
- When a file with the same name already exists in
_shared, the backup creates the symlink and downloads nothing, unless the file is shorter than Telegram's declared size (see A file cut short). - A new download is hashed. If a file with identical content already exists for the same account, that file is reused and the new copy is deleted. Content deduplication never reuses files across accounts.
- Where symlinks are not supported, the file is copied into the chat folder instead. The shared file stays in
_shared, since another chat may already link to it.
A missing shared file
A chat folder link whose _shared file is gone is a broken link: the row says the file was downloaded, and nothing is behind it. A row can also point at a chat folder that never held its file. Archives from before 4.0.5 kept a channel's files under its plain id (media/1234567890/), and migration 013 moved the rows' paths to the marked id (media/-1001234567890/) without moving the files.
The archive repairs both without asking Telegram when a copy is already on disk. It looks under the same name elsewhere in _shared, in the chat's other id-form folders (N, -N and -100N), and at any other row with the same content hash. A copy without a recorded hash counts only when the name carries a Telegram file id and the size matches. The copy is hardlinked, or copied where hardlinks are not supported, to the path the link names, and the link itself is never rewritten. Nothing that exists is replaced.
With no copy on disk, the row is marked not downloaded and the next backup downloads it from Telegram. The download fills the _shared file under the name the link holds.
A row is marked only when its file is provably gone: the media folder is there and not empty, and the folder the row points into exists under it. A media volume that is not mounted, or a network share that dropped, makes every file look missing, so on that evidence no row changes. A row whose folder is gone, or whose path lies outside the media folder, is left as it is too.
Three places repair: check-media checks every row and repairs with --repair, VERIFY_MEDIA repairs what it finds, and the transcription drain repairs a file before it sends it. Without VERIFY_MEDIA, a backup run that reads a downloaded row behind a broken link fetches it again, where the media settings allow, and ends with one warning: how many it met, and the check-media command to run. It counts only the rows the run reads, so run check-media to find the rest. A link into another store that this process cannot follow, such as a git-annex object outside the mount, is never touched. Locations, contacts, polls and the other metadata-only kinds have no file at all, so an old .bin path or link on such a row is never repaired or fetched. The map picture of a location is not checked either: when it is gone from the disk, the viewer shows the card without it.
A file cut short
Telegram declares the exact size of every document, and of every rendition of a photo. A download that ends below it stopped early, and the backup and the real-time listener treat it as a failure, never as a finished file. The backup tries it again within the same run and, if it is still short, records it not downloaded so a later run retries it under MEDIA_MAX_DOWNLOAD_ATTEMPTS. The listener stores nothing.
A release from late 2025 did store some of these short files as complete. Such a video has no playable end and its transcription fails. Run check-media to find them, and check-media --repair to mark them to download again. The marked file stays where it is until the new download arrives.
When the backup meets an existing file shorter than Telegram's declared size, it downloads the file again instead of reusing it. It replaces the short file only when every byte the short file holds is also the first bytes of the new download, so the replacement loses nothing. The replacement is one atomic rename of the same name, so every chat folder link and every row that pointed at the short file now reads the complete one, and no link is rewritten. When the bytes differ, the short file and every link to it are left exactly as they are. The complete download is kept beside it under the same name with part of its hash before the extension, and the row names that new file.
With DEDUPLICATE_MEDIA=false, files go straight into media/<chat_id>/. A file that already exists there is never downloaded again, unless it is shorter than Telegram's declared size.
Copy with symlinks intact
Use rsync -a or cp -a to copy the archive. Tools that follow or drop symlinks break the chat folders. See Backing up the archive for the full directory tree.
File names
A file with an original name is saved as <file id>_<original name>. MEDIA_MAX_FILENAME_BYTES defaults to 143. The backup keeps 40 bytes of that for a temporary suffix it adds during download, and shortens the name to fit the rest.
A file without an original name is saved as <file id>.<ext>, or <message id>_<media type>.<ext> when there is no file id. The extension comes from the MIME type, with a per-type default when it is unknown. The backup removes path separators from names. It also replaces characters that Windows forbids in file names with _, and puts _ in front of names that Windows reserves.
Avatars
Profile photos go to media/avatars/users and media/avatars/chats, one file per photo id, in the small size. The backup checks each avatar on every run and downloads only when no file exists for the current photo. An empty file is downloaded again.
Custom emoji
A custom emoji is the premium kind from an emoji pack. When the archive first sees one in a reaction or in a message's text, it notes the emoji's id and then fetches the file into media/_emoji, named after that id: <id>.webp for a picture, <id>.tgs for an animated one and <id>.webm for a video one, each about 100 by 100 pixels and a few tens of kilobytes. One file serves every chat and every account. The backup run fetches the emoji noted since the last run. With the listener on, a custom emoji first seen live is fetched within about five minutes instead, so it does not wait for the next scheduled run; the listener skips that step while a backup run is in progress, and leaves the retries to the backup runs. The backup asks Telegram for 100 ids per request and fetches at most 500 files per run and account; the rest wait for the next run. It is always on, like profile photos: DOWNLOAD_MEDIA and DOWNLOAD_MEDIA_TYPES do not apply, since the file is the same public file for everyone. It is skipped when the media folder is missing or empty where the backup runs.
A file already on disk is never written again. An id Telegram leaves out of its answer is asked for at most three times, and a failed download is tried three times too. A download that ends before the size Telegram declares counts as failed and is not kept, so a cut file never stands in for the emoji. A file of another kind or larger than 512 KB is not fetched. backfill-details --apply asks again for the ids that gave up.
Old flat layout
Archives from before the hash buckets kept every shared file directly in media/_shared/. The first backup or scheduler start moves them into buckets and rewrites the chat symlinks. It runs once. Files that fail to move are retried at the next start.
Old temporary suffixes
Before 7.11.3, a download could keep a temporary suffix, so a file was saved as <name>.<number>.<number>. At the start of each run, the backup looks for such names in the chat folders and in media/_shared. It renames each file to its clean name and points the chat symlink or the database path at it. It never deletes a file. When the pass finishes without errors, it writes media/_shared/.repaired-175-v2 and skips the check on later starts. Keep that marker when you copy the archive.
Retries
Within a run
A single file gets up to MEDIA_REFRESH_MAX_ATTEMPTS attempts in one run, 3 by default, including the first. This covers:
- When Telegram's download link for the file has expired, the backup fetches the message again and retries at once.
- When Telegram reports that the file is stored elsewhere, the backup fetches the message again and retries after a wait that grows with each try.
- When a download times out, the backup retries it.
Three settings limit the time spent on one file:
| Variable | Default | Effect |
|---|---|---|
DOWNLOAD_TIMEOUT_SECONDS |
3600 |
Limit for one download attempt. 0 disables it. |
MEDIA_REFRESH_TIMEOUT_SECONDS |
120 |
Limit for fetching the message again. |
MEDIA_FLOOD_SLEEP_THRESHOLD |
60 |
The backup waits out a FloodWait of up to this many seconds without stopping the transfer. |
Time spent waiting out a FloodWait during a download counts toward DOWNLOAD_TIMEOUT_SECONDS. If your account hits FloodWaits often, raise both together.
Across runs
A failed download leaves a pending row. A failed download of a file a row already holds, at a path that is not provably empty (the media folder is not there, or the row's folder is gone), leaves the row as it was. At the end of every run, a retry pass takes up to 1000 pending rows for each account, fewest attempts first. Each failed retry adds one attempt. A message that was deleted, or no longer carries media, also spends an attempt. After MEDIA_MAX_DOWNLOAD_ATTEMPTS failed attempts, 5 by default, the file is no longer retried.
The run logs a warning with the number of files that gave up. Archive status in the viewer counts them as "Gave up after retries". See Archive status. The viewer reads MEDIA_MAX_DOWNLOAD_ATTEMPTS to count these files, so set the same value in the viewer's environment block. See Environment variables.
Verify files on disk
VERIFY_MEDIA=true checks every downloaded file after the retry pass:
- A file that is missing, empty, or more than 1% off its recorded size is downloaded again.
- A missing file, a broken link included, is first restored from a copy on disk. See A missing shared file.
- A symlink into
_sharedwhose shared file is gone is a missing file. Other symlinks are trusted and not checked. - A damaged file is moved aside to
.verify-bakand put back if the new download fails. - A missing file whose download fails goes back to pending, so the retry pass picks it up, when its folder exists under the media folder.
- Chats in
SKIP_MEDIA_CHAT_IDSare skipped. - When the media folder is missing, unreadable or empty, verification is skipped with a warning and nothing changes.
Verification reads every media row on every run. Turn it on for one run after a disk problem or a restore, then turn it off again.
Parallel downloads
Large files can be fetched over several connections at once. This is off by default.
| Variable | Default | Rules |
|---|---|---|
PARALLEL_DOWNLOAD_ENABLED |
false |
Turns the feature on. |
PARALLEL_DOWNLOAD_MIN_SIZE_MB |
20 |
Only files at least this large use it. The floor is 1. |
PARALLEL_DOWNLOAD_CONNECTIONS |
4 |
Clamped to 2 through 8. |
PARALLEL_DOWNLOAD_PART_SIZE_KB |
512 |
4, 8, 16, 32, 64, 128, 256 or 512. Other numbers snap down to the next valid size, values below 4 become 4, and a non-number becomes 512. |
Each file being downloaded uses extra memory equal to the number of connections times the part size. At the defaults that is 2 MB. The file size alone decides whether a file uses parallel download, so large photos use it too. The scheduled backup uses parallel downloads. The listener always uses one stream.
The backup falls back to a single stream when parallel download cannot work:
- the file size is unknown;
- the file is stored on another Telegram data centre;
- a chunk comes back short or empty;
- the chunks leave a gap;
- the extra connections cannot be set up;
- the platform has no
os.pwrite, such as Windows, or the installed Telethon lacks the internals parallel download needs. Either turns parallel downloads off for the rest of the run.
A FloodWait, an expired download link or a file stored elsewhere goes to the normal retry loop, which restarts the whole file.
Thumbnails
The media gallery shows WebP thumbnails. Two places make them.
After each download, the backup tries to write a 200 px thumbnail under media/.thumbs/200/<chat_id>/. If that fails, the backup carries on, and the viewer makes the thumbnail later.
The viewer creates any missing thumbnail on demand, at 200 or 400 px, in WebP at quality 80. It applies these limits:
| Source | Limit |
|---|---|
| Images | Up to 50 MB and 25 megapixels |
| Videos | Up to 200 MB. The viewer uses ffmpeg to grab the frame at 1 s, or at 0 s if that fails. It gives up after 15 s. |
| Concurrency | Up to 8 image and 2 video thumbnails generated at once |
| Failures | Remembered for 300 s before the viewer tries again |
Without ffmpeg, the viewer shows no video thumbnails and reports no error. Both Docker images include ffmpeg. A native install needs it on the PATH.
The viewer keeps its thumbnail cache in the first of these that works:
THUMBNAIL_CACHE_DIR, when set;media/.thumbs, when writable;/tmp/telegram-archive-thumbs.
When the cache is anywhere other than media/.thumbs, as with THUMBNAIL_CACHE_DIR set, the viewer ignores the thumbnails the backup wrote under media/.thumbs and makes its own there.
Docker Compose
To use THUMBNAIL_CACHE_DIR, add it to the viewer's environment block. See Environment variables.
Why media is missing in the viewer
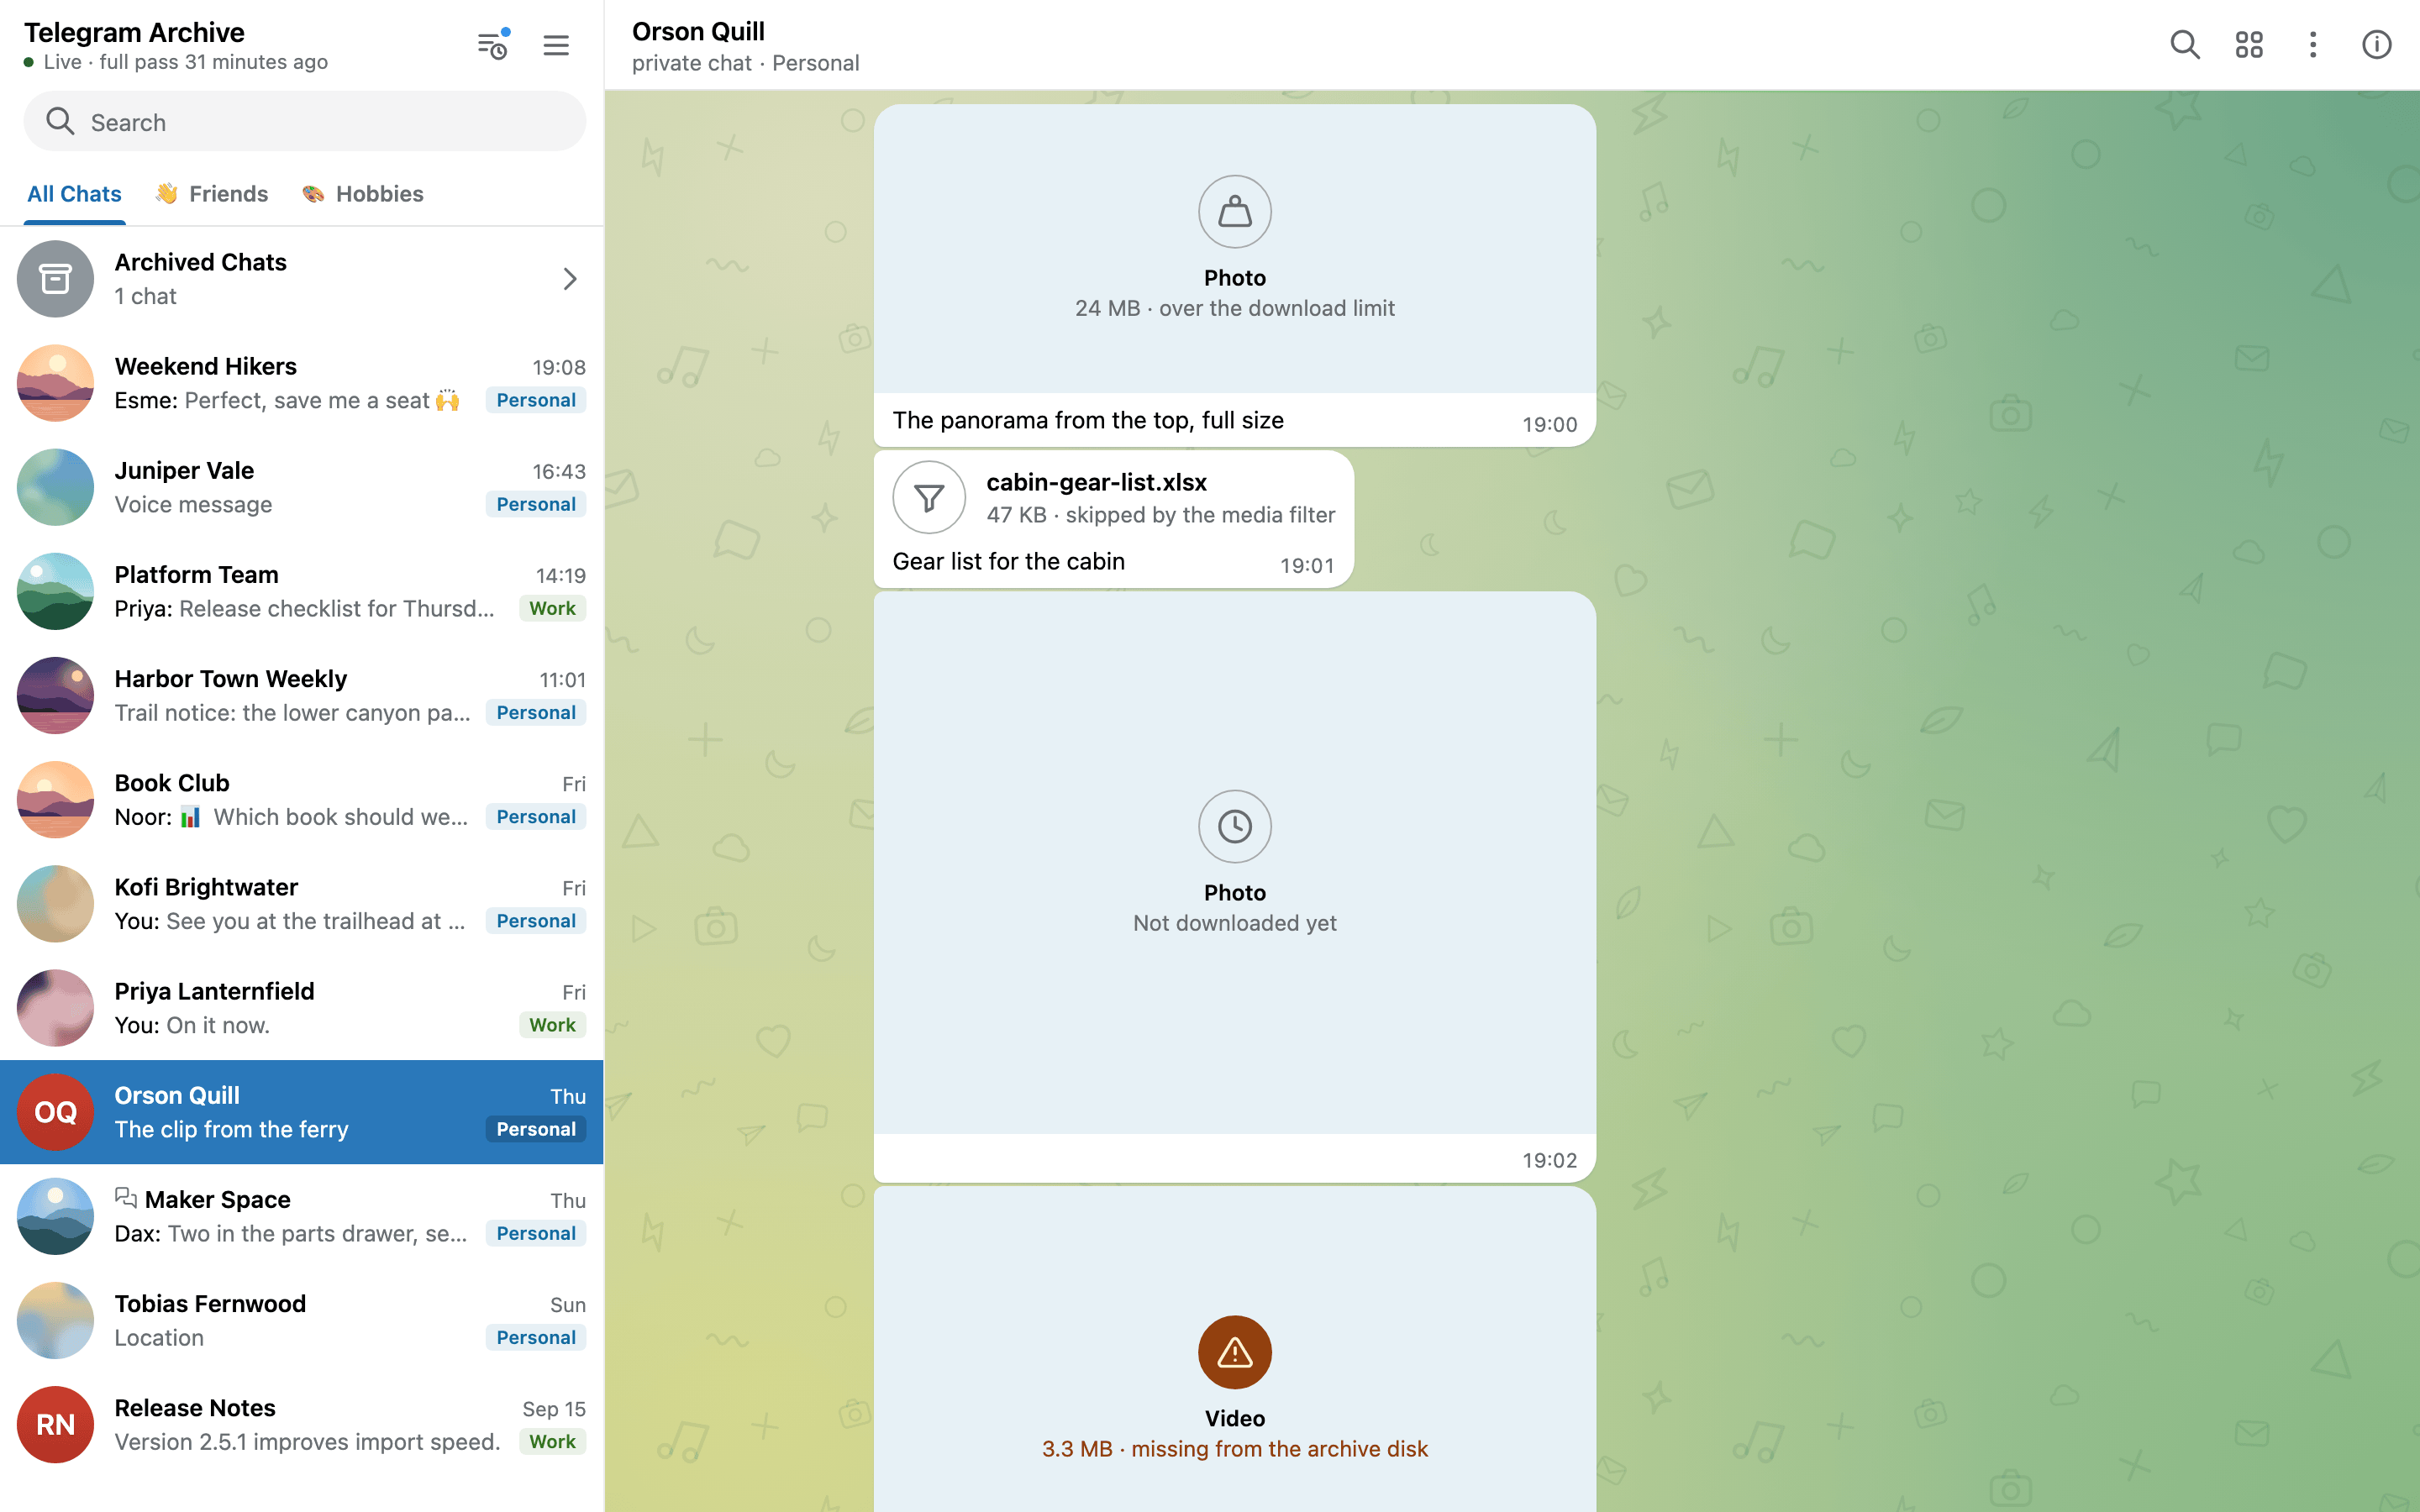
A message whose file the viewer cannot show keeps its place: a placeholder in the shape the media would take, with what it is and why, and the size when the archive knows it, for example Photo over 24 MB · over the download limit.
| Viewer text | Meaning |
|---|---|
| over the download limit | Skip reason oversize. Raise MAX_MEDIA_SIZE_MB to fetch it. |
| skipped by the media filter | Skip reason filtered. Relax DOWNLOAD_MEDIA_TYPES or DOWNLOAD_DOCUMENT_MIME_TYPES, or remove the chat from SKIP_MEDIA_CHAT_IDS. |
| hidden for this login, hidden for this link | The viewer account or share token has downloads off. A share-link session reads "link". The file may be archived. See No-download logins. |
| not downloaded yet | The row is pending. The retry pass picks it up, until it gives up. Archive status counts the files that gave up. A file check-media --repair marked to download again, such as one cut short, reads this way too, even while its old bytes are still on disk. The viewer does not load those bytes. |
| missing from the archive disk | The row says the file was downloaded, but the viewer could not load it: the file was moved or deleted outside the archive. |
Media from the real-time listener
The listener saves new messages as they arrive and downloads their media at once, by the same rules as the backup. With LISTEN_NEW_MESSAGES_MEDIA=false it leaves the media for the next scheduled backup. See Real-time listener.
Round videos in older archives
Archives captured before 8.5.0 stored round video messages as ordinary videos. The telegram-archive reclassify-round-videos command corrects them in place without downloading anything. See Import and maintenance tasks.